Skip to content

The ROI of Low-Code Development

Most low-code ROI content is unusable because it presents vendor-supplied averages as though they were your numbers. A percentage drawn from a survey of a thousand companies tells you nothing about whether your specific application will pay for itself. What does tell you that is a return model built from your own figures β€” the hours currently being spent, the errors currently being made, the decisions currently being delayed β€” measured before you build and again afterwards. This page sets out how to construct that model and what typically drives the return.

Why Most Low-Code ROI Claims Are Not Worth Reading

Why Most Low-Code ROI Claims Are Not Worth Reading

The problem with published low-code return figures is not that they are invented β€” it is that they are averages across wildly dissimilar situations, and the variance around them is larger than the figures themselves. A business replacing a manual process consuming forty hours a week has a completely different return profile from one replacing a process consuming four. An application that reduces an error rate with direct financial consequences behaves differently from one that improves a report’s timeliness. And the same application delivers different returns to two businesses depending on what their staff would otherwise be doing with the recovered time. A number that averages across all of this is not a forecast for you. What is usable is a model with your own inputs, and the discipline that makes it credible is measuring before you build. This is the step almost universally skipped: businesses know a process is painful without knowing how many hours it consumes, how often it produces errors, or what those errors cost. Spending a week establishing the baseline before the project starts is what converts an ROI claim from an assertion into an observation, and it is the difference between a business case that survives scrutiny and one that does not.

What’s Driving This Decision?

The question arrives in two forms. The first is justification β€” someone needs to approve spending and wants a defensible number rather than a conviction. Here the value of a proper model is partly the figure and partly that the assumptions are visible, so the person approving can challenge the inputs rather than having to accept or reject a conclusion. The second is prioritisation: several processes could be automated, budget exists for one, and the question is which produces the best return. That comparison is only meaningful if each candidate is measured the same way, which again requires baselines.

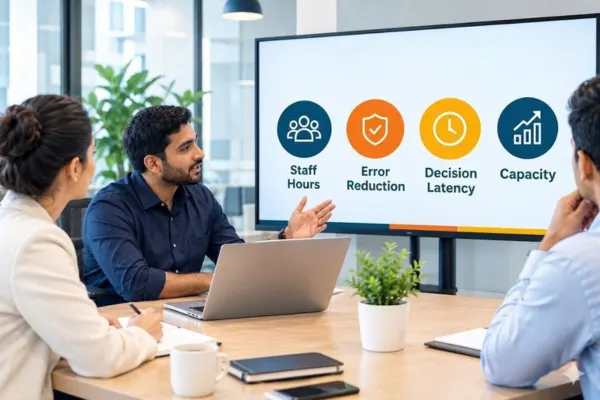
What consistently drives return in the applications we build is narrower than the marketing suggests. Recovered staff hours are the most visible component and usually not the largest. Error reduction is frequently larger, because manual processes produce errors with costs that are real but uncounted β€” a wrong quantity dispatched, a missed renewal, an invoice raised at the wrong price, a claim window missed. Decision latency is the third and the hardest to quantify but often the most valuable: a margin figure available during the quarter rather than after it changes commercial behaviour in ways a monthly report cannot. And the fourth is capacity β€” the ability to handle more volume without proportional headcount, which matters most to businesses that are growing. A model that counts only recovered hours will usually understate the return substantially, which is ironically why some genuine business cases fail to get approved.

Factors Affecting Low-Code ROI

What Drives the Outcome?

Digital transformation value depends on more than the software. The real outcome comes from time recovered, errors reduced, faster decisions, and added capacity, measured against investment and adoption. These are the key factors we consider when assessing the potential return and business impact:

Baseline Measurement Before the Build

The input everything else depends on. Hours consumed by the current process, error frequency and cost, reporting latency, and volume handled per person, established before development starts rather than estimated afterwards.

Recovered Staff Hours and What They Become

Hours no longer spent on manual entry, reconciliation, chasing, and report assembly β€” valued honestly at what those people will actually do instead, which is redeployment rather than headcount reduction in most businesses.

Error Reduction and Its Real Cost

The errors a manual process produces and what each costs: rework, wrong dispatch, missed claim windows, incorrect pricing, lost renewals. Usually larger than the hours component and almost always uncounted beforehand.

Decision Latency Improvement

The commercial value of information arriving during a period rather than after it. Harder to quantify than hours but frequently the largest component, particularly where the figure concerned is margin, stock, or credit exposure.

Capacity Without Proportional Headcount

The volume the business can handle with the same team after the change. For growing businesses this is often the real return, and it is invisible in a model that only counts current-state savings.

Build Cost Against Ongoing Platform Cost

The one-time development cost and the recurring subscription, modelled separately because they behave differently over the payback period and beyond it.

Time to Value

How quickly the return starts. A low-code build reaching production in weeks begins returning within the same quarter, which materially affects payback period compared with an approach delivering in nine months.

Adoption Rate and the Realisation Gap

The gap between the modelled return and the realised one, which is almost entirely an adoption question. An application used by half the team returns roughly half the model, and this is the factor most often left out of a business case.

Zoho Applications We Use for This

These Zoho applications support different parts of the transformation and help measure where the business impact comes from. We use each where it best supports the process, measurement, and outcomes being targeted:

Zoho Creator
Zoho Creator

The build platform, where the return comes from targeting a specific process rather than a broad programme

Zoho Analytics
Zoho Analytics

Baseline and post-implementation measurement, which is what makes the return observable rather than asserted

zoho books
Zoho Books

Where error cost is financial and the improvement is measurable in the accounts

Zoho CRM
Zoho CRM

Where the return is conversion, follow-up discipline, or retention rather than operational hours

Zoho Inventory
Zoho Inventory

Where the return is stock accuracy, reduced holding, or lower write-off

zoho people
Zoho People

Where the return relates to utilisation, attendance, or workforce capacity
Where This Applies?

This applies to any business building a case for a specific application rather than for low-code as a concept. It is most useful where the current process is measurable β€” manual data entry, reconciliation, chasing, report assembly, and error correction all produce hours and incidents that can be counted with a week of observation. It is less useful where the benefit is genuinely qualitative, and in those cases an honest model says so rather than manufacturing a number.

It applies with particular force to prioritisation. Where several processes are candidates and budget covers one, measuring each the same way makes the choice evidential rather than political β€” and it frequently reorders the list, because the process people complain about most is not always the one costing most.

It also applies after the fact. Businesses that built an application without establishing a baseline cannot demonstrate the return, which makes the next investment harder to approve. Measuring the current state of an existing application against a reconstructed baseline is imperfect but usually possible, and it is worth doing before the next business case is written.

Ready to Build a Model You Can Defend?

A return assessment establishes your baseline β€” hours, errors, latency, and volume on the process concerned β€” models the expected improvement with the assumptions visible, and sets up the measurement that will show what actually happened. Where the honest conclusion is that the return does not justify the build, we will say so; that is a cheaper outcome than discovering it after delivery, and it usually redirects the budget to a process where the case is stronger.
Why Choose Techvaria for Low-Code Development ROI

Why Choose Techvaria for This?

Techvaria is a Zoho Premium Partner and Odoo Silver Partner delivering operational applications in India and the UAE. We measure before building because a return nobody baselined is an opinion, and we would rather your next business case rested on evidence from the last one. We do not publish borrowed averages as though they were forecasts for your situation, and where an assessment concludes that a process is not worth automating, that conclusion is the deliverable. We also assess process volume, error frequency, staff time, decision latency, adoption, and ongoing platform costs before estimating potential returns. This gives businesses a clearer view of where value will come from, what needs to change operationally, and how the expected return can be measured after implementation rather than assumed at the outset.

Hear From Our Clients

Industries We Serve

Frequently Asked Questions

Because the variance around published averages is larger than the averages themselves, so a figure drawn from someone else’s survey is not a forecast for your application. What is defensible is a model built on your measured baseline with the assumptions visible. That takes about a week to establish and produces a number that survives scrutiny from whoever has to approve it.

Usually not, though it is the most visible. Error reduction is frequently larger, because manual process errors have real costs β€” rework, wrong dispatch, missed claim windows, incorrect pricing β€” that nobody counts. Decision latency is often larger still, and capacity matters most to businesses that are growing. A model counting only hours typically understates the case substantially.

It depends entirely on the process, which is why we model rather than quote. What can be said structurally is that low-code shortens payback compared with longer development approaches, because production in weeks means the return starts in the same quarter. The variable that most affects realised payback is adoption, not build cost.

With the same measures as the baseline, taken after adoption has stabilised β€” typically two to three months post-go-live rather than immediately, since early figures reflect the learning curve rather than the steady state. Where the application generates the data directly, the measurement is built in rather than a separate exercise.

Hours consumed by the current process, broken down by activity. Error frequency and the cost of each type. How long it currently takes for the relevant information to reach whoever acts on it. And the volume handled per person. A week of structured observation is usually enough, and it is the most valuable week in the project.

By being clear about what those people will actually do. In most businesses it is redeployment rather than headcount reduction, so the value is the output they produce instead rather than a salary saving. Valuing recovered hours at full salary cost when nobody is leaving produces a number that will not survive challenge, and overstating it undermines the whole model.

Then that is the recommendation. Some processes are genuinely cheaper to leave manual, particularly low-volume ones that are irritating rather than expensive. Establishing that before spending is a good outcome, and it usually redirects the budget to a candidate with a stronger case.

Because the model assumes the process is followed. An application used by half the team returns roughly half the modelled benefit, and the remaining half of the process continues to carry its original cost β€” often with the added cost of reconciling two ways of working. Adoption is the largest single variable between a modelled return and a realised one, which is why capture design and training are return factors rather than delivery details.

Resources

Latest Blogs